Most people type vague questions into ChatGPT and hope for the best. There's a better way.
New to the space? Our comparison database benchmarks 112 AI tools side by side, so you can see the differences at a glance.
The 4-Sentence Prompt Framework is a structure you can use in under 30 seconds — and it reliably produces better results from any AI tool.
The Framework
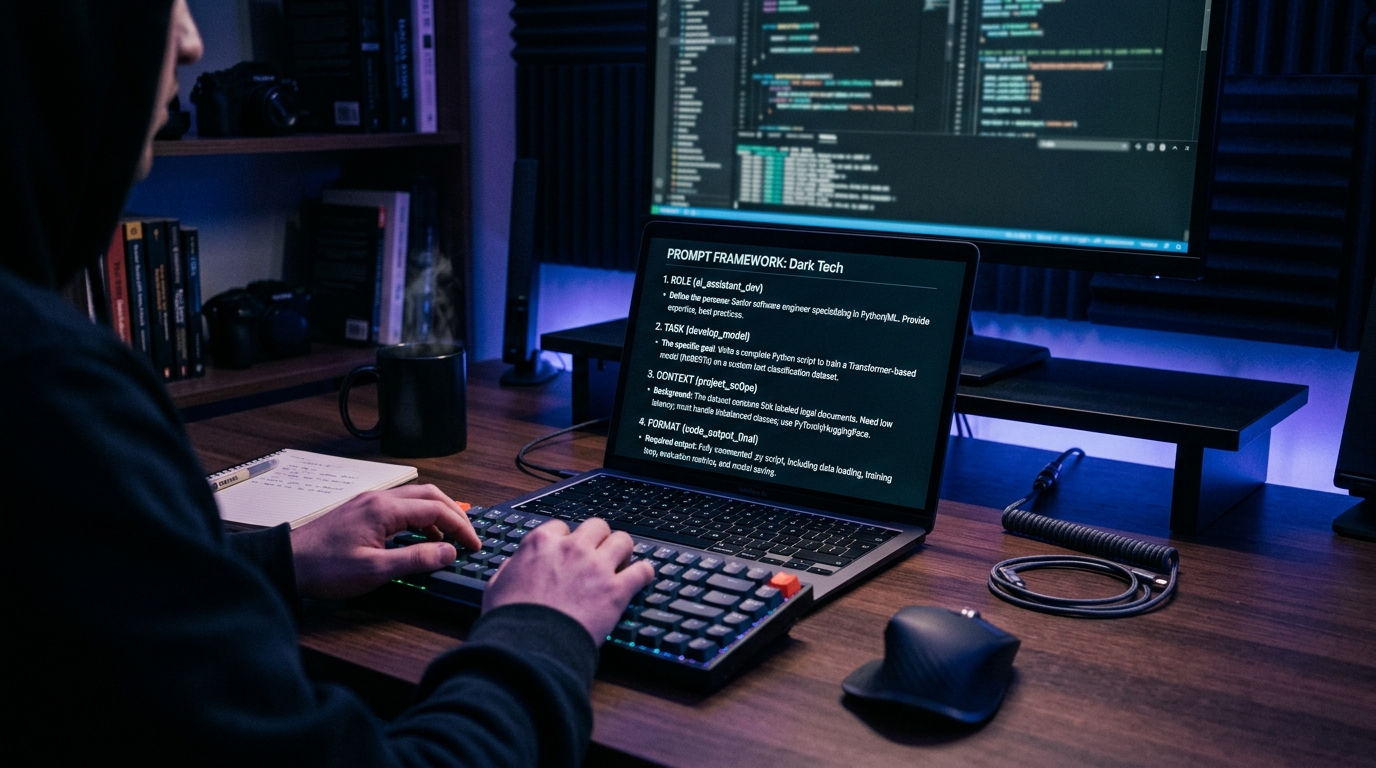
Every prompt you write should contain exactly these four sentences:
Sentence 1 — Role: Tell the AI who it is. "You are a senior software engineer..." or "You are a marketing copywriter..."
Sentence 2 — Task: State exactly what you need. "Your task is to review this error log and identify the root cause..."
Sentence 3 — Context: Give relevant background. "Here's what you need to know: the app is running Node 22 on Linux, and the error appears after ~4 hours of uptime..."
Sentence 4 — Format: Specify the output shape. "Output this as a bullet-point list with severity ratings next to each item."
That's it. Role, Task, Context, Format. Four sentences, four lines.
Why It Works
Language models are incredibly sensitive to how information is arranged in their context window [Anthropic: Prompt Engineering Guide]. When you front-load the role and task, the AI "sets" its behavior before processing your actual data. The format instruction at the end prevents the common problem of getting a wall of text when you wanted a table.
This framework works because it mirrors how humans follow instructions best: know your role, understand the assignment, get the facts, then deliver in the expected format. Research from OpenAI's prompt engineering guide confirms that structured prompts with clear context dramatically improve output quality across all major language models.
The Science Behind Structured Prompting
When you provide a role (Sentence 1), you're effectively priming the model's behavioral distribution. Studies on large language model behavior show that role-setting sentences activate specific knowledge domains within the model's training data, leading to more relevant and accurate outputs. The task sentence focuses the model's attention on the specific objective, while context provides the necessary constraints to prevent hallucination or irrelevant tangents.
Format specification is particularly important because language models have been shown to produce outputs that match the structural patterns you describe. By requesting a table, bullet list, or numbered format, you're leveraging the model's extensive training on structured documents — it will naturally organize information in the requested shape without needing explicit formatting instructions for every line.
Example
Here's a bad prompt versus a good one using this framework:
Bad:
"Can you look at this code and tell me if there are bugs?"
Good:
class="language-text">You are a senior code reviewer specializing in Python web applications.
Your task is to review this Django view function for security vulnerabilities.
Here's what you need to know: the function handles user file uploads and stores them in S3. Authentication is handled by a JWT middleware.
Output this as a numbered list of issues, each with a severity rating (Critical / High / Medium / Low) and a one-sentence fix recommendation.
The difference is night and day. The first prompt returns generic advice. The second returns actionable, structured output you can act on immediately.
Quick Reference
| Prompt Element | Purpose | Example |
|---|---|---|
| Role | Sets AI persona | "You are a data analyst" |
| Task | Defines the goal | "Analyze this sales data for Q1 trends" |
| Context | Provides background | "The data is from our CRM, exported as CSV" |
| Format | Shapes the output | "Output as a table with month-over-month changes" |
When to Use This Framework vs. Other Approaches
The 4-Sentence Prompt Framework works best for task-oriented prompts where you need specific, structured output. However, it is not the only effective prompting strategy. For creative writing or brainstorming, a more open-ended approach may yield better results. For complex multi-step tasks, consider combining this framework with chain-of-thought prompting or prompt chaining, where each step builds on the previous output. The key insight is matching the prompting strategy to the task complexity — simple queries need simple prompts, while complex tasks benefit from structured frameworks like this one.
Many advanced users combine the 4-Sentence Framework with system prompts in API settings. The role sentence maps naturally to the system message, while task, context, and format go in the user message. This separation keeps the behavioral priming in the system channel and the task-specific instructions in the conversation flow, giving you the best of both worlds.
Frequently Asked Questions
Do I really need all four sentences every time?
For simple questions like “what’s the capital of France?” — no. But for any task where quality matters, all four sentences pay for themselves in fewer iterations and better first results.
Can I combine Role and Task into one sentence?
Yes. “You are a data analyst tasked with reviewing Q1 sales trends” works. The framework is a mental model, not a rigid template. The key is ensuring all four pieces of information exist somewhere in your prompt.
Does this replace system prompts in APIs?
No. System prompts in API settings serve the same role as Sentence 1. If you’re using an API, put the Role in the system message and use the other three in your user message. Same structure, different channel.
Dig deeper: OpenAI Agents SDK review · Tip of the Day.
Back to all posts